 AI Tool Consultant
Real tasks
Tests use work from my own projects: a feature in a live product, a German correction, a structured extraction. A page only says "tested" for what I actually ran.
Comparisons written by someone who pays for these tools and uses them on real projects. Every page says what was tested hands-on and what comes from documentation, with the date next to every price.
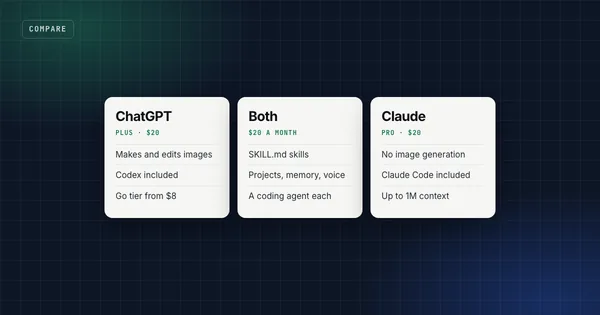
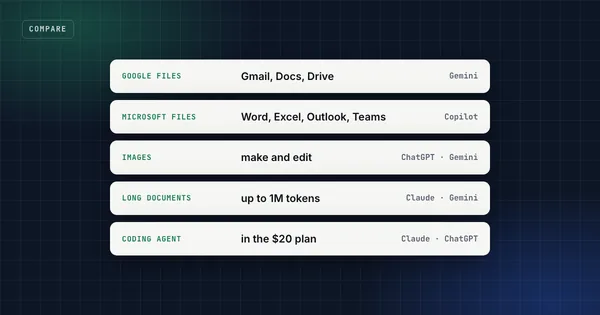
ChatGPT, Claude, Gemini and Copilot for everyday work: what each plan buys and which fits which job.
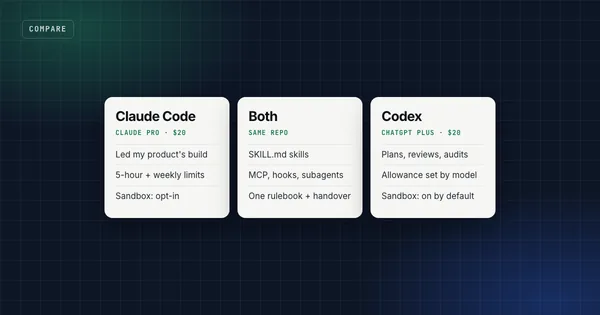
Claude Code, Codex and the agents around them, from using them on real products.
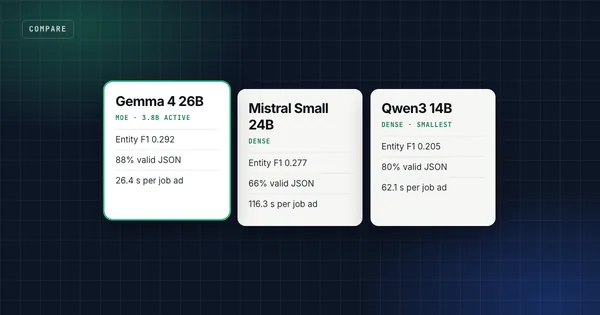
Open-weight models run on a laptop, measured on real tasks.
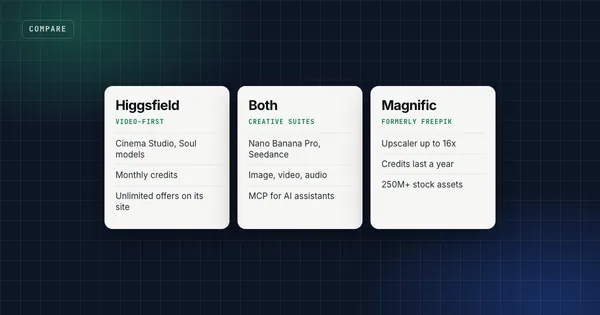
AI creative suites, upscalers and generators for pictures and clips.
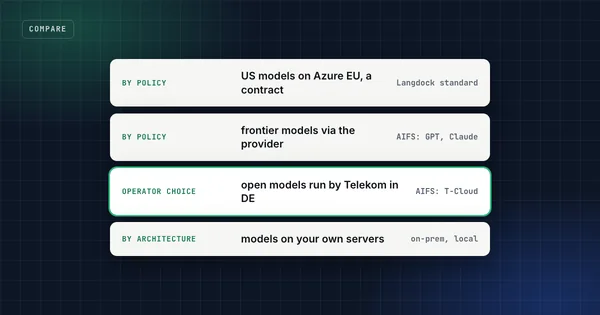
Workspaces that bring several models to a whole company, with admin and data controls.
Tests use work from my own projects: a feature in a live product, a German correction, a structured extraction. A page only says "tested" for what I actually ran.
Product facts link to the vendor's own documentation. Prices come from the vendor's pricing page, "as of" the day I read it. Benchmarks carry their name and date.
Nobody pays for a placement, and the links are plain links. Where my own skills fit a tool, the page says so and names them as mine.
Four free skills that work in Claude, Claude Code and Codex: a handover routine, a session-start checklist, a caption writer and an exam-prep tutor.